Six days ago I wrote three posts about Farside: what happens inside a research run, asking follow-up questions and research that runs on a schedule. That was the core of the product.
This week was about everything around the core. Where you use it from, how fast it answers, how hard it checks itself, and whether a company's security team will let it in the door.
#Research inside the tools you already use
Most people don't want another tab. They want the answer inside the thing they're already working in.
Farside has had an MCP server for a while. MCP is the standard way AI assistants and coding agents plug into outside tools. But until this week, connecting it meant creating an API key and pasting it into a config file. That's fine for developers. It's a wall for everyone else.
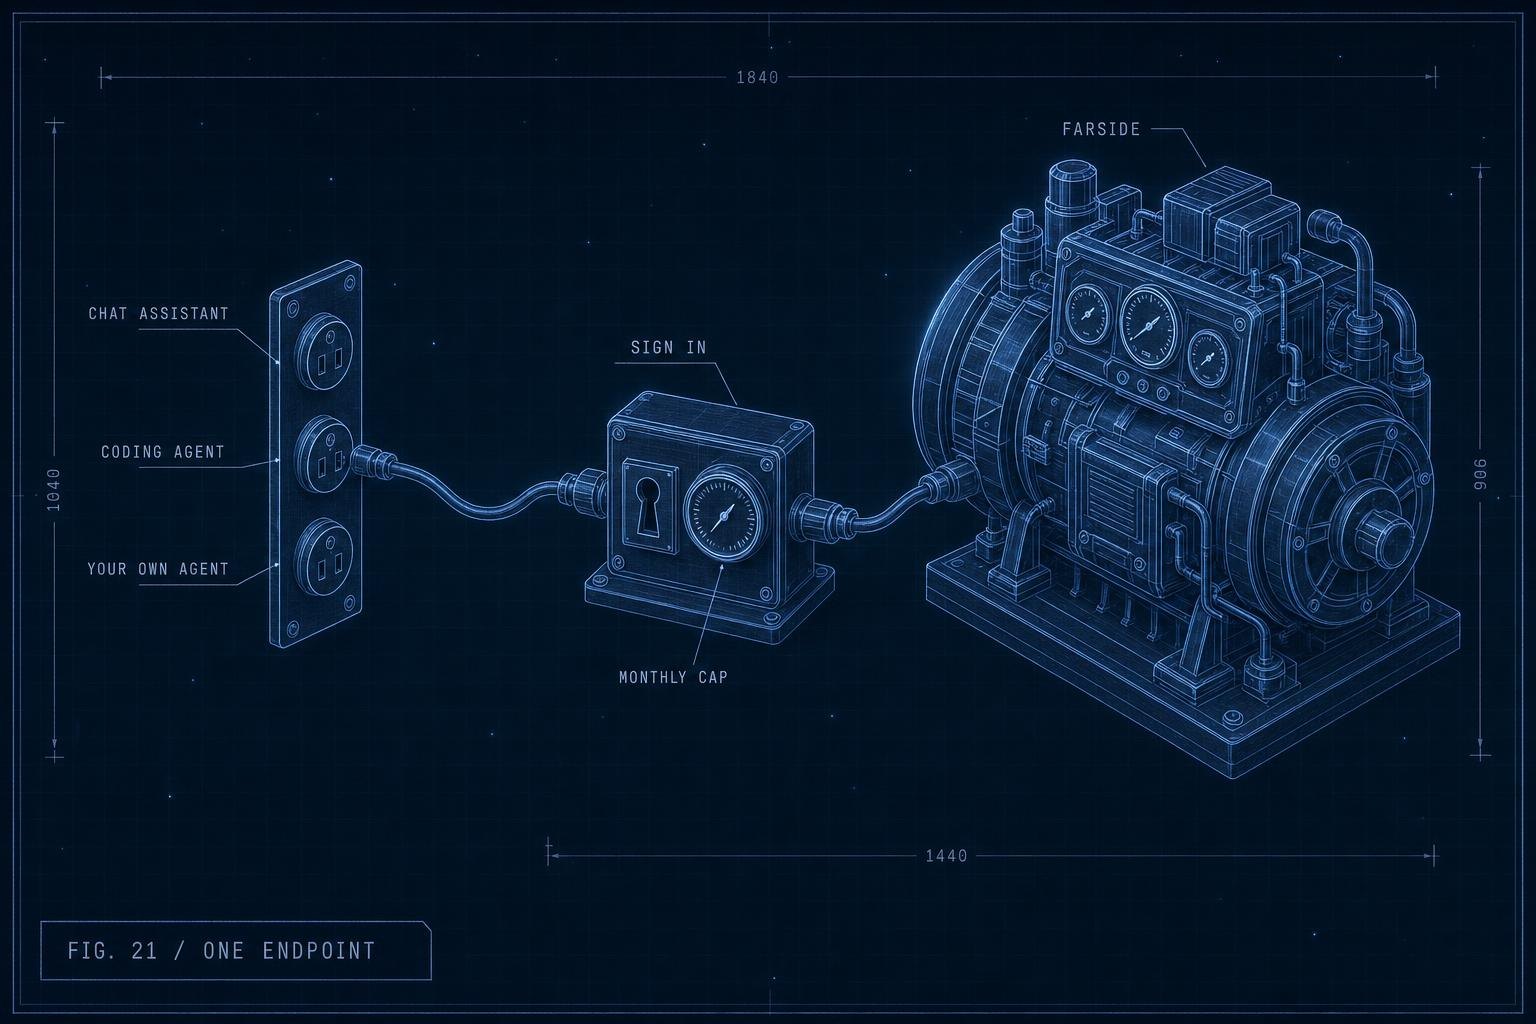
Now Claude.ai and ChatGPT can connect by signing in to Farside. You add Farside as a connector, sign in, and approve what it's allowed to do. No key to copy, nothing to paste into a file.
When you approve a connection, you choose three things:
- Which workspace it can see.
- Read or run. Read covers the free stuff: looking at your research, searching sources, checking costs and workflows. Run adds anything that spends credits, like starting a research run or asking a question.
- A monthly credit cap. That's the most the connection can spend in a month, whatever the assistant decides to do.
Under the hood it's standard OAuth with PKCE. Access tokens last an hour, and refresh tokens change every time they're used. If an old refresh token ever shows up again, which is what a stolen one looks like, Farside cuts off that whole connection. In ChatGPT it currently needs developer mode turned on in the connector settings.
You can see every app you've connected under Settings, then Connected apps, and revoke any of them. Revoking cuts it off right away, including any session it has open. Workspace admins get the same view across the whole workspace, with who connected each app, and can change any app's cap.
Claude Code, Cursor, Codex and anything else that takes an API key work the same as before. The MCP page has the exact setup for each one.
Once it's connected, the assistant can estimate what a question will cost, start a run, read the report and its sources, ask grounded follow-ups, build a dossier and read its documents, and run your saved workflows. Every tool now carries a plain title and hints about what it does: whether it only reads, whether it can spend credits, whether it reaches out to the web, and whether it can't be undone. Your assistant can use those to be careful with the expensive ones.
#Faster answers, on purpose
#Lite: a quick cited answer
Not every question needs the full treatment. Sometimes you just want a solid, sourced answer to something reasonably simple, and you want it now.
Lite is a new depth for that. It runs two quick rounds of research instead of a full investigation, and you still get citations you can click through to the source.
- Lite run
- 12
- Credits. Two quick rounds, cited answer
- Standard run
- 25
- Credits. The everyday depth
- Deep run
- 120
- Credits. The full investigation, now with more running in parallel
- Ask a follow-up
- Free
- Every plan gets free questions each day, then 1 credit a question
#Deep got faster
A Deep run does a lot of work: several rounds of searching, follow-up digging, and the documents for a dossier. Most of that used to happen one step at a time. A single round could take 14 to 17 minutes in production, mostly waiting on searches that ran one after another.
Now a round's searches run side by side, and so do the follow-ups and the dossier documents, with limits so we never hammer a source or a model provider. In a benchmark that replays production-shaped timings, a round went from 14 to 17 minutes down to about 3 to 4. That's a simulation, not a measurement of live runs yet, so I'll publish real numbers once enough Deep runs have gone through on the new code.
#Deploys don't kill your run
This one was a bad bug and I'm glad it's gone. On November 9, a Deep run in production got restarted by six deploys in a row because we kept shipping. Every restart counted as a failure and made the run plan its current round all over again.
Now a deploy asks the run to stop at its next safe checkpoint, puts it back in the queue without counting it as a failure, and the new version picks it up automatically, continuing the same round instead of starting it over.
#Reports that check themselves harder
A research report is only worth something if you can trust it, so a lot of this week went into catching the report's own mistakes before you see them.
- No contradicting itself. A new consistency pass catches a report that disagrees with itself, like a headline range that its own examples fall outside of, or one number wearing two different labels. It rewrites only the sentences it flagged, and every rewrite has to keep the same numbers, the same citations and the exact source quote, or it's thrown out. If the pass itself has a problem, it never fails a run you paid for.
- No orphaned sentences. When the number audit removes a sentence it can't back up, it now also removes the sentences that only made sense next to it. You won't see a lonely "These measure different things" pointing at nothing anymore.
- Numbers that point to the right place. The number audit already checked that every figure in a report matches its source. Now, when a cited source states that number about something else, the audit goes and adds the source that actually backs it up.
- "Disputed" means disputed. A claim is only marked disputed when sources actually disagree. Before, a messy page could make a claim look disputed when nobody really disagreed.
- Cleaner evidence. The quotes shown as evidence now come from the article itself, not from a page title or a navigation bar that got flattened into the text.
- Honest readiness scores. The score for whether a report is ready to act on had a problem: 19 of 26 production reports scored exactly 90. Three of its nine checks never really varied. Freshness, for example, was measuring when we fetched a page instead of when the page was published. Each check now earns partial credit from what it actually measures, so the score finally tells reports apart.
#Ready for a security review
The other half of the week went into what a company needs before it can roll a tool out to a whole team. These are on the Enterprise plan, except audit export, which starts at Team.
- Single sign-on. SAML 2.0 or OIDC, per organization, with accounts created on first sign-in and safe linking to accounts people already have. Farside warns you before your identity provider's certificate expires.
- SCIM provisioning. Add and remove users and groups from your identity provider, with group-to-role mapping. Removing someone removes their access everywhere in your organization.
- Workspace security policies. Verified domains, require SSO, an IP allowlist and a session length limit.
- Audit logs. Export them as CSV or JSONL, or stream them to your SIEM.
- Retention and legal hold. Choose how long data is kept, and put a hold on anything that has to be kept no matter what.
And to make sure all of that keeps working, there's now a canary that walks the whole enterprise journey in production every 30 minutes, using a test organization and a test identity provider. It verifies a domain, signs in with SAML and OIDC, provisions and removes users over SCIM, checks that a removed person really is locked out, connects an app, tests the security policies and plan limits, and exports and streams the audit log. If it fails twice in a row, we get an alert. I'd much rather it find a problem than you.
#What's next
Same as always: I want to know where it falls short. If you connect Farside to your assistant and it does something dumb, or a report gets something wrong, tell me. Every one of those becomes a fix and usually a check that stops it from coming back.
You can try Farside here, and the MCP page has setup for every client.